
The change was small on paper
In 2025 my team at Rocket India moved our Confluent Cloud Kafka estate from public endpoints to Private Service Connect (PSC). The applications did not change. Topics, schemas, ACLs and client code stayed the same. What changed was the network path between our workloads and the brokers.
That sounds like a configuration tweak, and it is, until you remember what sits on the other end. The cluster carried the mortgage servicing platform, which runs continuously, and 32 services across 8 teams depended on it. A networking change that touches every producer and consumer is a migration, whatever the diff looks like.
This article is the plan we followed, the commands we used, and the checks that told us it was safe to move on.
What PSC changes, and what it does not
Private Service Connect is a Google Cloud feature that gives you a private IP address inside your own VPC that maps to a service published by someone else. For Confluent Cloud, that means the brokers are reached through an endpoint in your network rather than through a public address.
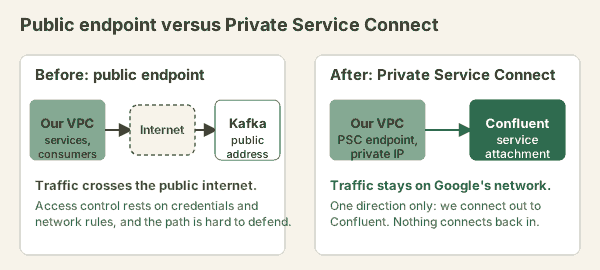
- What changes: the bootstrap address, DNS resolution for the broker hostnames, and the path packets take.
- What does not change: the Kafka protocol, topic design, consumer group semantics, authentication, and the client libraries.
- Direction: connections are one way. Our workloads open connections to Confluent, and Confluent does not open connections back into our VPC.
The part that needs care is that the networking mode of a Confluent Cloud cluster is chosen when the cluster is created, so a cluster on public endpoints cannot simply be switched. We stood up a new PSC-enabled cluster and moved traffic across to it. That is where the rest of this article comes from.
Migration architecture: blue and green side by side
The principle is to run two clusters in parallel and move work across in small, reversible steps. We called the existing public cluster blue and the new PSC cluster green.
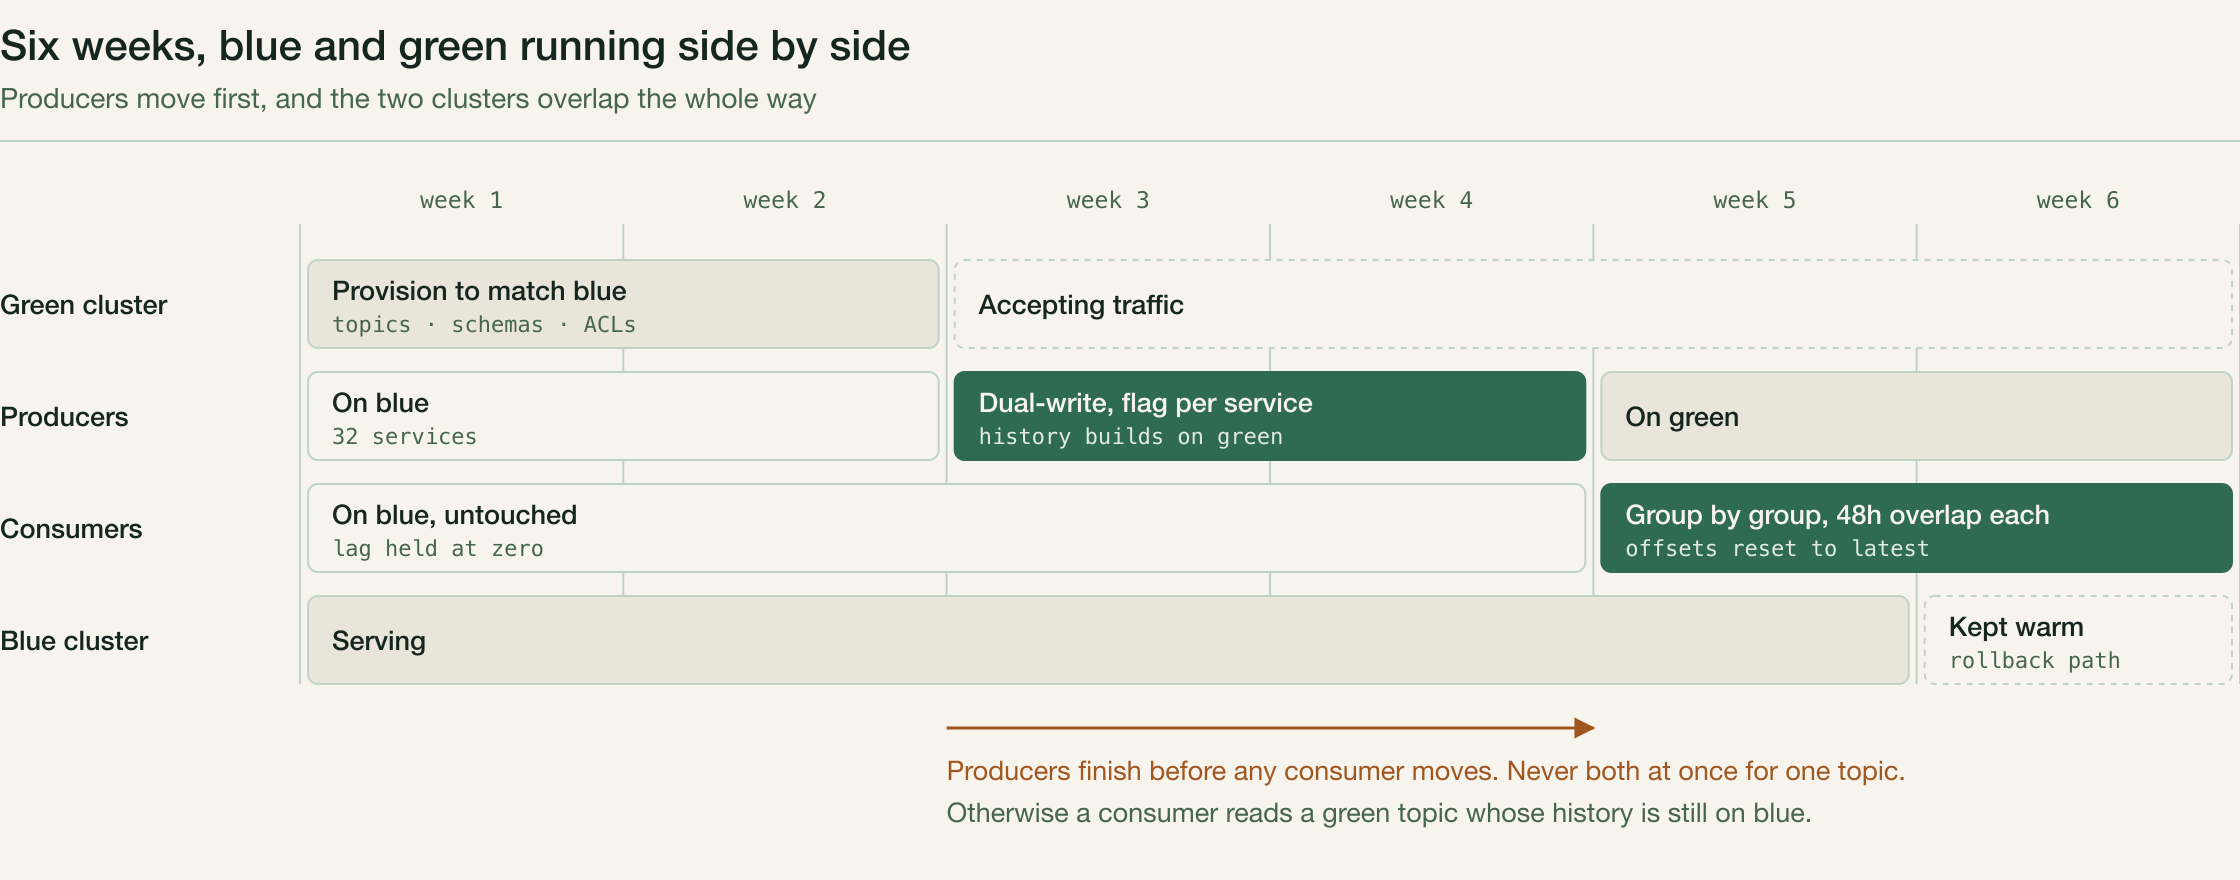
Phase 1: provision green (weeks 1 and 2)
We built the PSC cluster next to the existing one and made it match:
- Identical topic configuration: partition counts, replication factors and retention policies
- Schema Registry contents brought across so both sides agree on every schema
- The same ACLs and service accounts
- Dashboards for both clusters in New Relic, so one screen showed blue and green together
- Connectivity checked from a pod in every consumer service
The connectivity check matters more than it looks. With PSC the broker hostnames must resolve to private addresses from inside the pod, and a port that answers is not enough on its own. We checked both:
# From a consumer pod: does the hostname resolve to a private IP?
kubectl exec -it <consumer-pod> -- nslookup <bootstrap-hostname>

# Does the port answer on that address?
kubectl exec -it <consumer-pod> -- nc -zv <bootstrap-hostname> 9092
Phase 2: producers first (weeks 3 and 4)
We moved producers before any consumer. That let green build up message history before consumers arrived, which later became our replay buffer.
- Catalogue the producers. 32 services across 8 teams wrote to Kafka.
- Put the broker URL behind a feature flag. Each producer already read its bootstrap servers from an environment variable, so the PSC endpoint became a flagged override.
- Shadow-publish critical topics. For loan events and customer updates, a small wrapper wrote every record to both clusters with identical keys.
- Check blue is still healthy. Consumer lag on blue had to stay at zero before we called a producer done.
// Producer dual-write wrapper (simplified)
public void send(ProducerRecord<String, Object> record) {
    blueProducer.send(record);      // public endpoint cluster
    if (pscFeatureEnabled) {
        greenProducer.send(record); // PSC cluster
    }
}
Lag alone does not prove the two clusters agree, so we also compared message counts per topic per hour across both. A wrapper bug or a slow cluster shows up there first.
Phase 3: consumer groups (weeks 5 and 6)
This was the most delicate phase. We moved consumer groups team by team, with a 48-hour overlap for each.
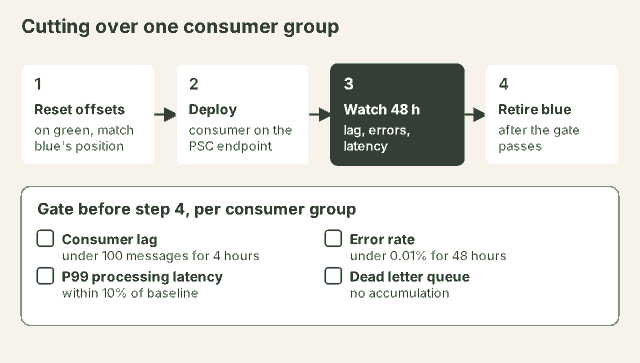
- Reset offsets on green to match the group's position on blue. The tool is
kafka-consumer-groups --reset-offsets, and for groups that needed an exact position we reset by timestamp. - Deploy the consumer on green with
bootstrap.serverspointing at the PSC endpoint. - Watch for 48 hours: lag, error rate and processing latency.
- Retire the blue consumer only after the gates pass.
The rule I would not break: never migrate producers and consumers of the same topic at the same time. Finish producers, let history build on green, then move consumers. If something goes wrong you still have a buffer to replay from.
The hard cases
Exactly-once producers
Several critical producers used Kafka transactions. Transactional state belongs to a cluster, so these needed their own handling:
- New unique
transactional.idvalues on green, to avoid any collision with blue - No dual-write for these producers, because a transaction cannot span two clusters
- A hard cutover in a low-traffic window, Sunday between 2 and 4 AM
- Blue kept available for 72 hours afterwards as the rollback option
Schemas
Rather than recreate schemas by hand, we exported them from the blue registry and imported them into green:
# Export schemas from the blue registry
confluent schema-registry cluster export --config blue-config.properties > schemas.json

# Import into the green registry
confluent schema-registry cluster import --config green-config.properties --file schemas.json
Consumer groups with long retention needs
Some groups, mainly analytics and audit, needed to replay 7 to 14 days of history. For those we:
- Kept blue running for 14 more days after their migration
- Set green offsets to the equivalent position with a timestamp reset
- Ran a one-time replay from blue to green to fill any gap from the dual-write window
Monitoring and rollback
We wrote the success and rollback criteria down before the first move, not during it.
Success criteria for each consumer group
- Consumer lag under 100 messages for 4 consecutive hours
- Error rate under 0.01% for 48 hours
- P99 processing latency within 10% of baseline
- No dead letter queue accumulation
Automated rollback trigger
# New Relic alert condition: rollback trigger
SELECT count(*) FROM KafkaConsumerMetrics
WHERE consumer_lag > 10000
AND cluster = 'green-psc'
SINCE 15 minutes ago
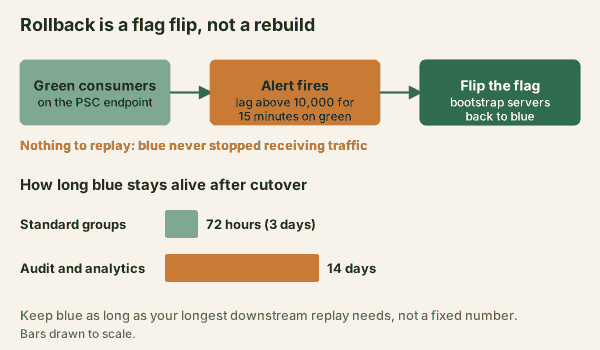
Because blue kept receiving every write, a rollback is a flag flip rather than a rebuild. How long blue stays alive after a cutover depends on the longest replay any downstream job needs.
Results
The migration finished two months ahead of schedule.
- No planned downtime. Producers and consumers kept running through each step, and each team moved on its own release cadence.
- Private network path. Traffic to the brokers no longer uses the public internet, and the connection is one way, from our VPC out to Confluent.
- Schemas intact. Every registered schema came across without a version conflict.
- Counts compared, not assumed. We checked hourly message counts per topic across both clusters in addition to lag.
Lessons
- Producers before consumers. Consumers then arrive to a full history on the new cluster.
- Everything behind a flag. Broker URLs, schema registry URLs and consumer group IDs should all be configuration.
- Write rollback criteria first. You will not think clearly about them mid-migration.
- Shadow-publish the topics that matter. The cost of dual-writing is small next to the safety it gives.
- Automate offset resets. Doing them by hand across many groups invites mistakes.
- Publish the calendar early. All 8 teams knew the plan six weeks ahead.
- Check DNS, not just ports. With PSC, the first thing that goes wrong is usually a hostname resolving to the wrong place.
The same sequence works for a Kafka version upgrade or a move between clouds. Only the reason for standing up the second cluster changes.
References
- Google Cloud, Private Service Connect overview, cloud.google.com
- Confluent, Schema Registry cluster migration, docs.confluent.io
- Apache Kafka, Exactly-once semantics, kafka.apache.org/documentation
- Confluent, Consumer group offset management, docs.confluent.io
Frequently asked questions
What happens if a rollback is triggered mid-migration?
Because producers dual-write during the migration window and the blue cluster stays live until validation passes, a rollback is a feature-flag flip: point consumers back to the blue bootstrap servers and disable the PSC override. Nothing needs to be replayed or reconstructed, because blue never stopped receiving traffic. This is why the dual-cluster strategy costs more upfront than a hard cutover. The rollback path has to be this cheap or the plan does not hold up under pressure.
How long should the blue cluster stay alive after cutover?
We kept it running for 72 hours after standard consumer cutovers and 14 days for consumer groups with longer retention or audit requirements. The right window is whatever your longest downstream replay requirement is, not a fixed number. If an analytics job only reprocesses the last 24 hours, 72 hours of overlap is generous. If a compliance job replays 14 days on demand, blue needs to survive that long.
What actually changed for the applications when moving to PSC?
Only the network path: the bootstrap address, DNS resolution for the broker hostnames, and the route packets take. Topics, schemas, ACLs, authentication and client code stayed the same. That is why the work was mostly sequencing and verification rather than code changes.
Does this approach work for a version upgrade instead of a networking change?
Yes. The dual-cluster, producers-before-consumers sequence does not care why you are standing up a new cluster, whether that is a new networking model like PSC, a major version upgrade, or a move between clouds. The mechanics (shadow publishing, offset alignment, rollback triggers) are the same.
What is the biggest risk in the producer migration phase?
Silent divergence between blue and green during dual-write. If the wrapper that writes to both clusters has a bug, or one cluster falls behind under load, green can look healthy on lag metrics while missing messages. We compared message counts per topic per hour across both clusters, because lag alone does not tell you whether the two clusters agree on what happened.